The most controllable expressive voice model

  • 55+ languages
  • Broadcast quality 48 kHz
  • Emotion direction
  • Sound effects

A voice actor that understands what you ask for. Direct it in your own words.

Try it now
Voyager 1

Don’t write voice.Direct it.

You have a script and you know exactly how it should sound.

Until now, that meant wrestling with a synthesiser.

With Voyager 1 you do what a director does in the studio: tell the actor what you want, and listen.

Same text. Four takes.

[sarcastic, like you saw it coming] Oh, brilliant. Heading out with no map and no fuel was going to go great.

The text is the same. You choose the performance.

Pick a take

More examples

Sound effect: Owl Fearful Gasp What... what was that? Sound effect: Thunder Pause Holy cr*p! Wh... what is going on? Sound effect: Branch snapping Th... that's not an owl, I... I think. Sound effect: Footsteps on leaves Someone's close by. Sound effect: Zipper Sound effect: Dog barking Gasp Astonished Oh my God!... it's Cookie! Serene Sigh aww, poor baby! You got so scared come on, come here. very tenderly Sigh Lie down right here, sweetie.

Scene · one scriptBrooke · a stormy night

Voice, effects and ambience. The scene, finished.

Fear, surprise and tenderness in one scene; an owl, thunder, a branch, footsteps on dry leaves and a dog, each in its place, in the middle of a storm. You write it in the script and it comes out mixed, ready to deliver.
Measured quality

On par with the leaders. Measured, not promised.

We put Voyager 1 through the same public benchmarks MiniMax and Fish Audio use to publish their numbers, with the same method: a transcriber listens to every clip and counts the words it drops, swaps or makes up.

Word error rate · EnglishSeed-TTS benchmark · 1,088 sentences, single take
Lower is better

Of words spot on in English: clearer than a person recorded on the same test.

  • Voyager 11.53%
  • MiniMax-Speech1.65%
  • Drama 31.83%
  • Human recordingA person, same text2.13%

One take per sentence, failed ones not redone. seed-tts-eval normalisation.

Naturalness · EnglishUTMOS, 1 to 5 · Seed-TTS benchmark
Higher is better

More natural than a person recorded on the same test.

  • Voyager 13.96
  • Human recordingA person, same text3.53
Reliability · Spanish and EnglishOur own test set · checked by hand

0 failures in 480 plain and emotion-tagged sentences: not one with anything skipped, repeated or made up.

  • Plain sentences · Spanish0 of 160
  • Plain sentences · English0 of 160
  • With emotion tags0 of 160

Sources and method. Our own measurement of Voyager 1 in production, 21 October 2026, with the same method as the published figures (seed-tts-eval): Whisper-large-v3 transcribes every clip and we compute the word error rate (WER). English: Seed-TTS-eval test-en (1,088 sentences, one take each, seed-tts-eval normalisation); its human recordings, measured the same way, score 2.13% against the published 2.14% (arXiv:2406.02430). Naturalness is measured with UTMOS22 (1 to 5). Competitor figures: MiniMax-Speech in its best mode, arXiv:2505.07916 (table 1); Fish Audio Drama 3, arXiv:2610.18010 (section 5.4, non-streamed takes; regenerating failed takes, the report gives 1.54%, table 4). Reliability: our own test set checked by hand, with 40 plain sentences per language and 40 with emotion tags, each read by four catalogue voices. Logos are trademarks of their owners and only identify each system.

How we measure it

  1. The same test

    The public sets MiniMax and Fish Audio use to publish their numbers: 100 sentences in Spanish and 1,088 in English.

  2. A transcriber listens

    Whisper transcribes every clip and we count the words the model drops, swaps or makes up. Lower is better.

  3. Against a person

    The human recordings from the same test, measured the same way, so every number has a reference.

Just like in the studio

Walk out of the studio with finished audio: voice, sound effects, ambiences and post-production, ready to deliver.

Ask for sound effects and ambiences in your own words, in the script or to the AI assistant, and they come mixed with the voice. It understands requests written in more than 30 languages.

Talk to it like an actor.

Write the intention in brackets, in your own words and your own language: [like you’re teasing them], [holding back tears, but smiling]. Voyager 1 understands what you mean and performs it.

32
EnthusiasticIronicFriendlyUrgentNostalgicThreatening+26

32 emotions, one click away.

Excitement, irony, tenderness, urgency, nostalgia, menace… Switch register mid-paragraph, with no cuts or seams.

Emotion intensity

Dial how hard each emotion lands.

Line by line: from natural to maximum.

Also through the API and the MCP: your agent sets the intensity of every line.

[crying] I didn't think you'd actually come back.

Emma · EN-US
Emotion intensityNewNatural
[laugh][belly laugh][sigh][deep breath][ahem][voice cracking]+12

What makes a voice human.

Laughs, belly laughs, sighs, breaths, an ahem before the bad news, a voice that cracks. 18 effects that turn a reading into a performance.

And the winner is[pause 0.8 s]you.

Rhythm, to the millisecond.

Exact pauses where you need them, and the speed you want. Silence can be directed too.

[Customer service, warm and unhurried; softer on the refund line]
Thanks for calling. I’m listening.warm
I’ve checked your order.unhurried
We’re refunding you today.softer

Direct the whole scene.

One direction for the whole block: “Customer service, warm and unhurried; softer on the refund line.” Voyager 1 applies it line by line.

Post-productionComedy club + Audience laughter

“Last night I said, out loud, ‘I’m so hungry.’ This morning? Pizza ads. On my phone, on my TV… on my fridge. My fridge is judging me now.”Devin · stand-up, deadpan

Make it sound like it’s there.

Phone, PA, a cave or a comedy club with its crowd: pick where it happens and the take sounds right there. Effects don’t change the take or cost anything, and what you download comes signed.

Your voiceRecording · 0:08
Under 10 s
or
800+voices in the library

Your voice, cloned from under 10 seconds.

Record or upload under 10 seconds of your voice and your clone is ready to direct. Prefer another? Choose from 800+ voices in the library, with accents from every region.

Dialogue · two voices
HannahEnthusiastic Alright, alright! Give it up for… Danny Reyes!
DevinChuckle Whoa. Okay. The mic is more excited than I am.
DevinIronic This morning? Pizza ads.

Several voices in one piece.

Each block with its own voice, pauses and overlaps to the millisecond, and an audience that laughs right on cue. This stand-up set came out of the studio in one piece, with no outside editing.

Reviewvoicefinder.io/review/…
Client · block 2Shall we try a warmer take here?
Approved

Your client listens and approves.

Send a link to listen to the piece and approve it. Your team comments block by block, and you decide who pays for what gets generated.

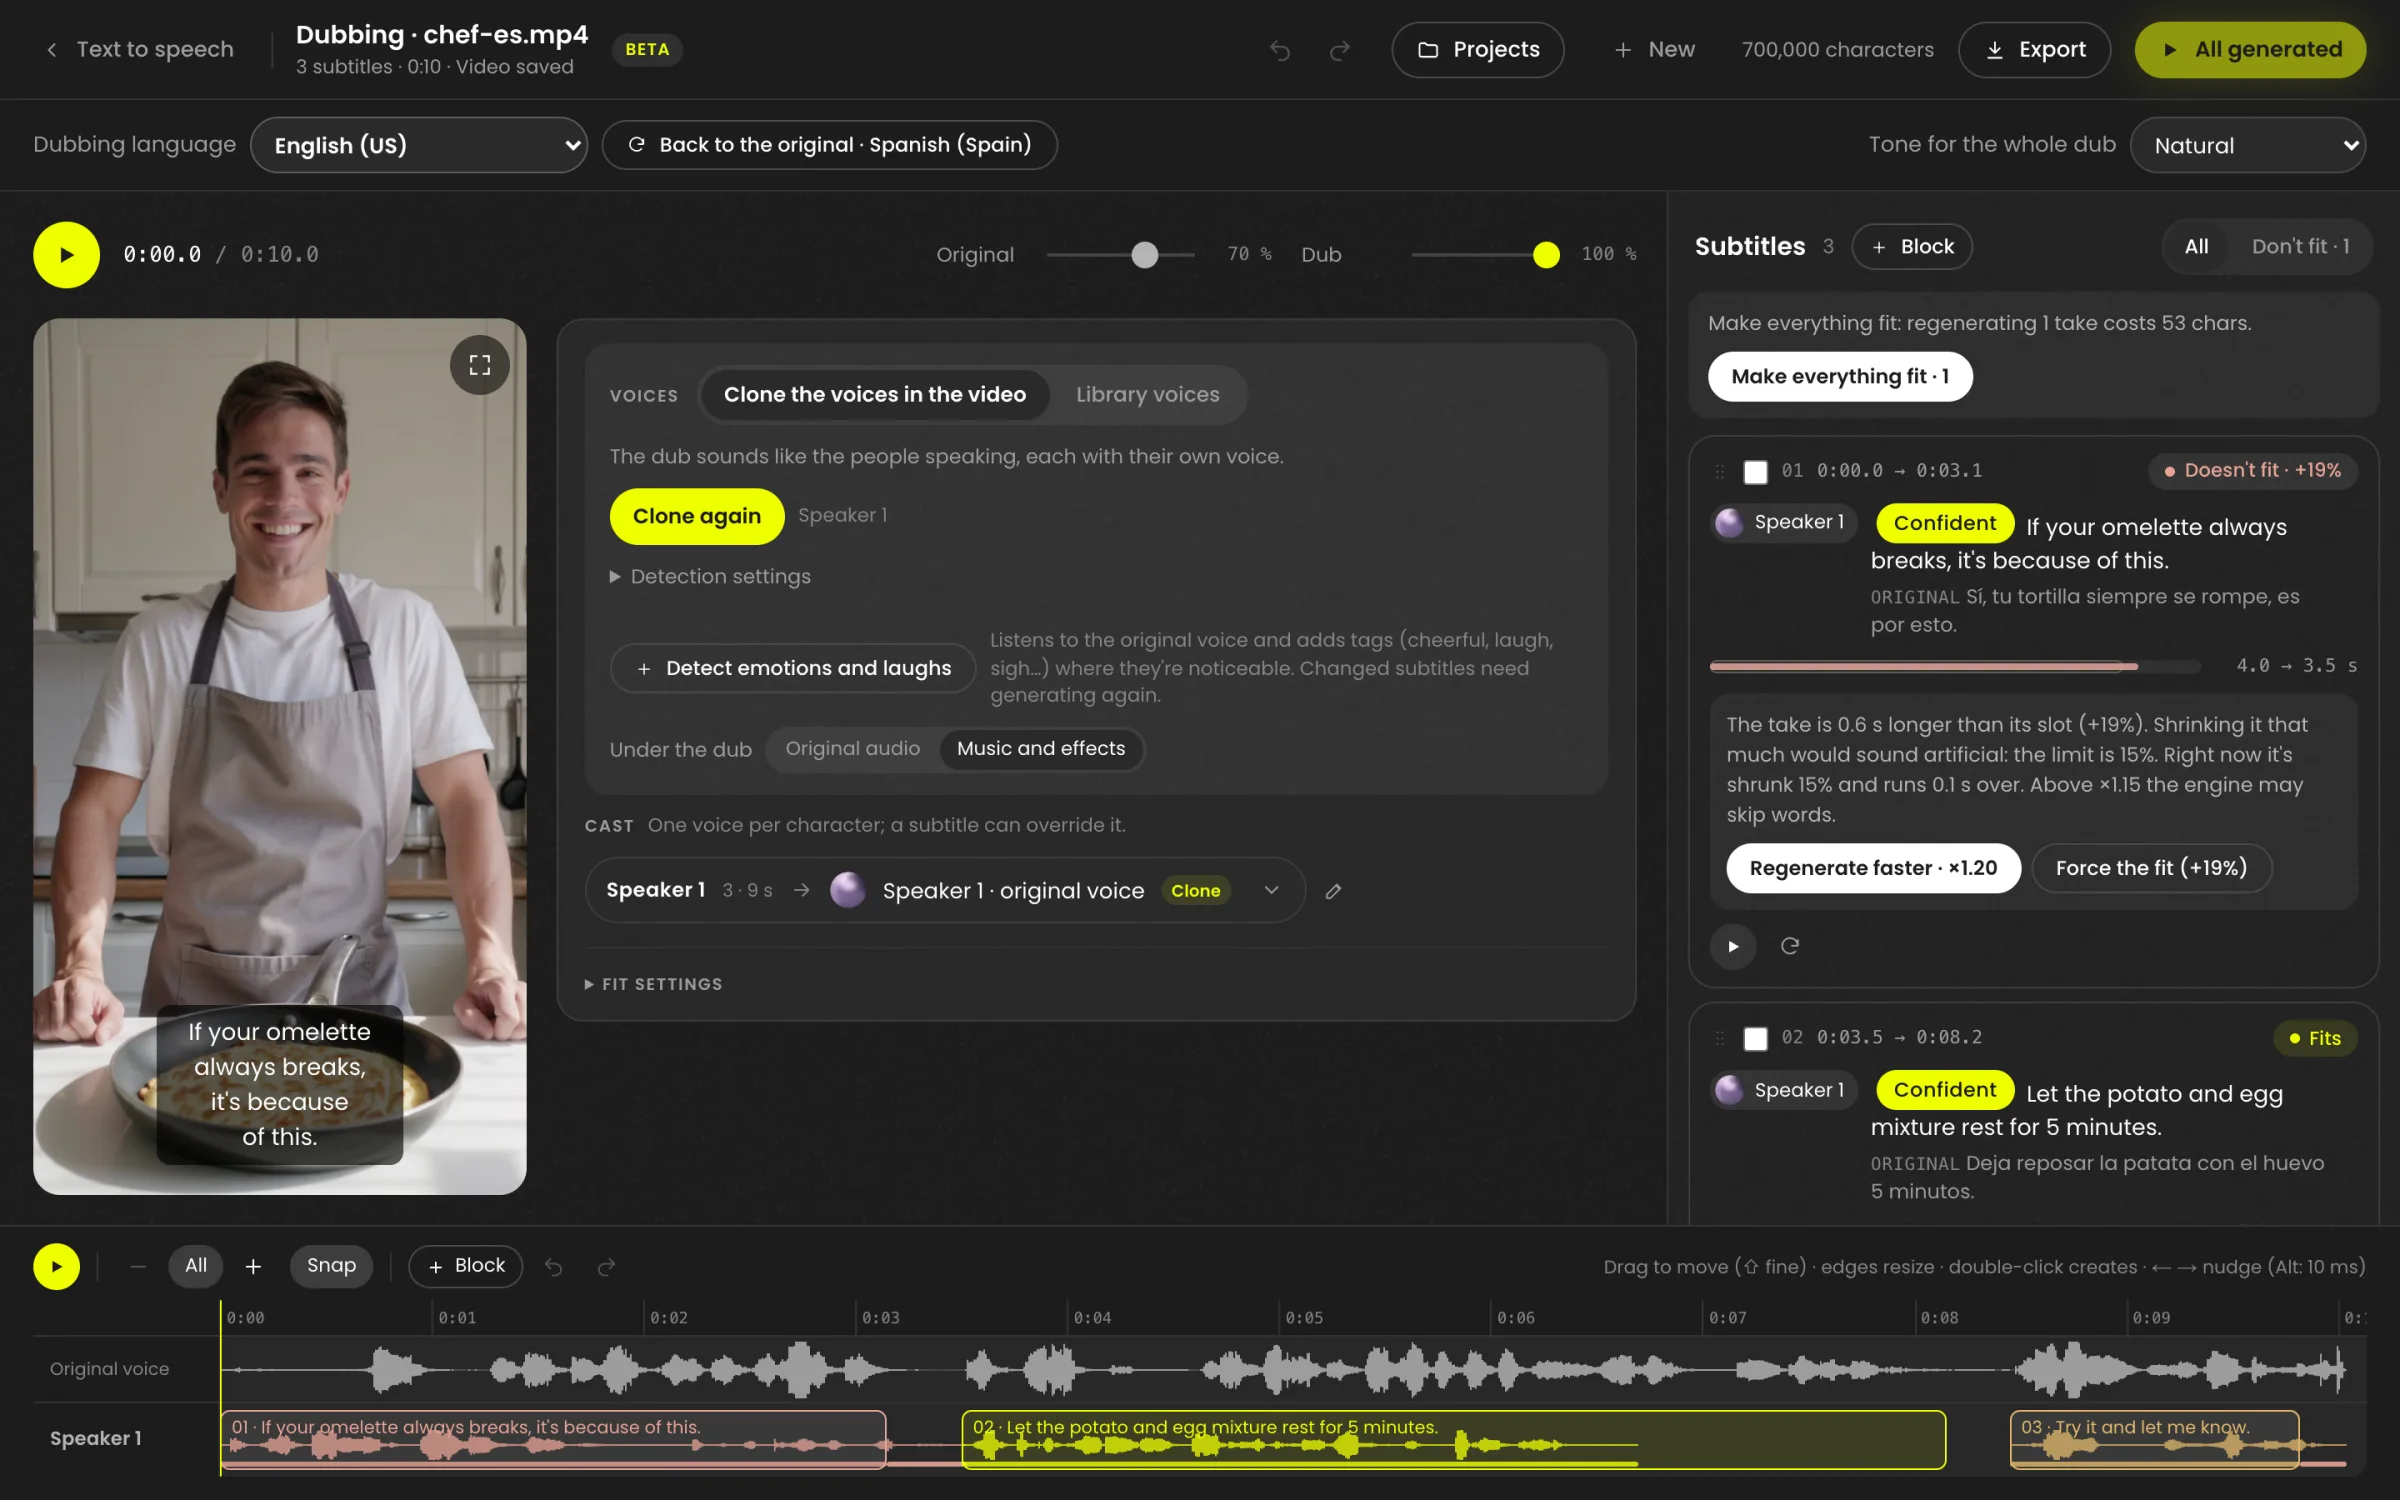
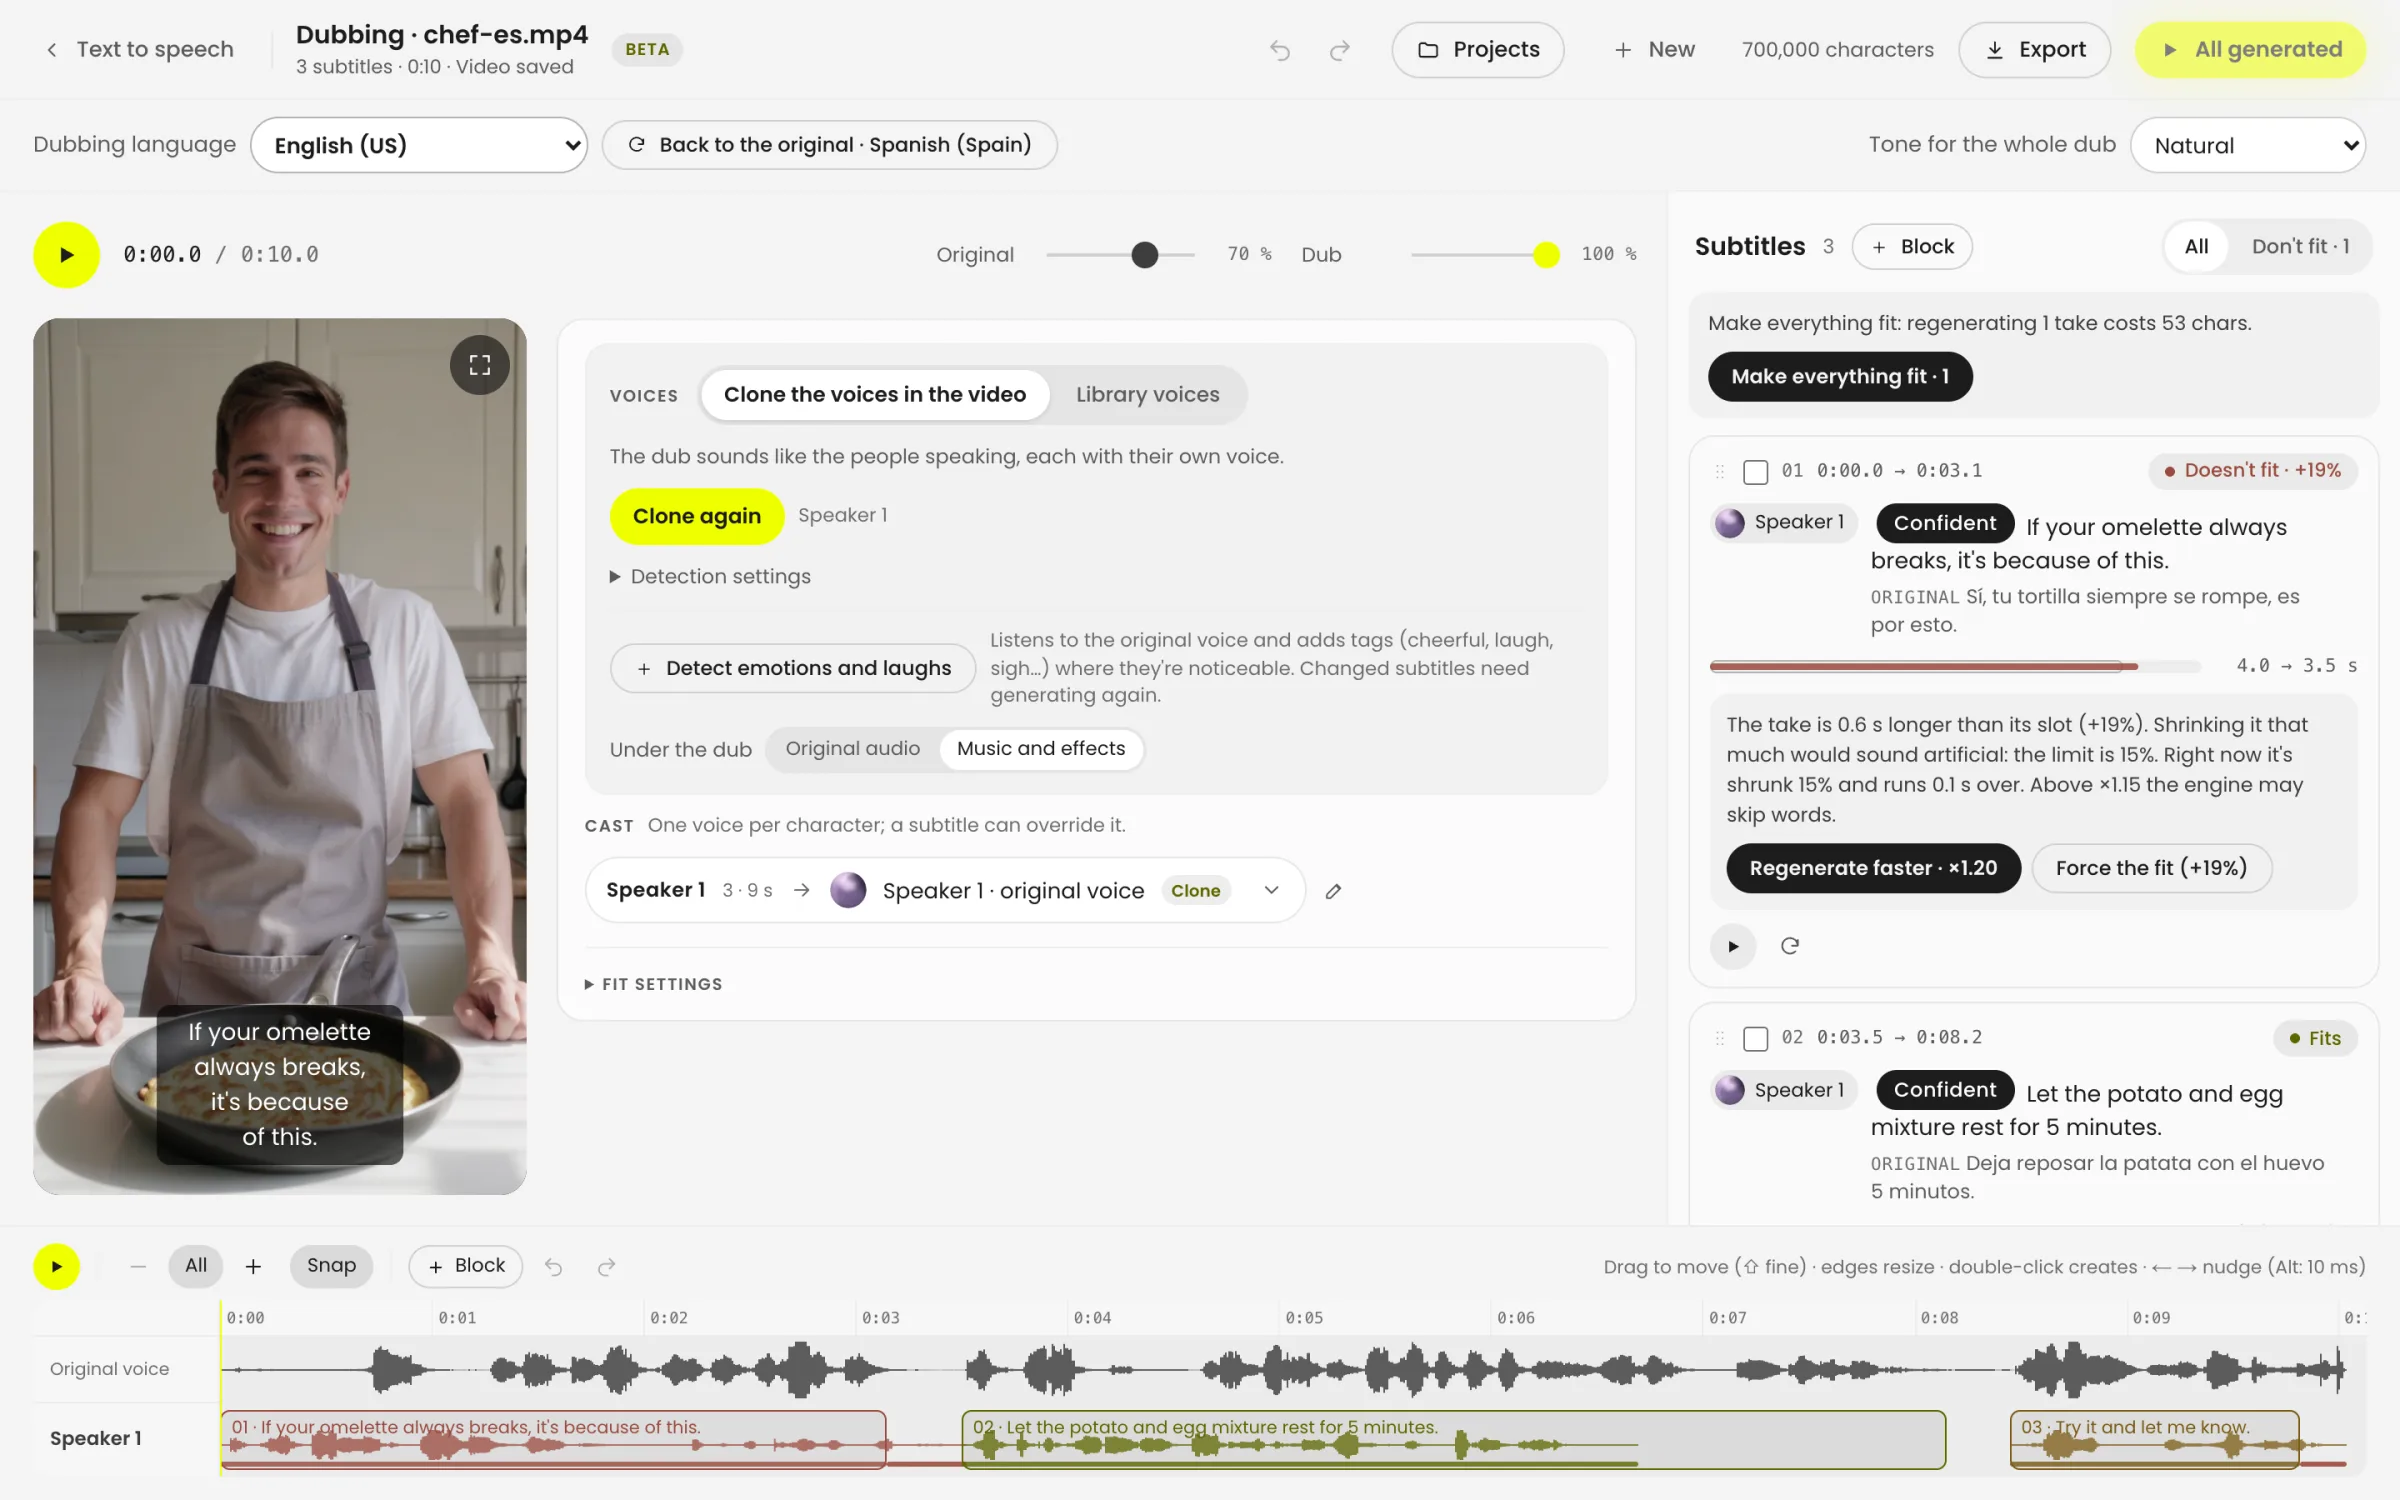
The dubbing studio with the video, the cast and the subtitlesThe dubbing studio with the video, the cast and the subtitlesSpanishEnglish
AI dubbing

Your video, in another language. In its own voice.

Upload a video or paste a link. It detects who's speaking, clones each voice, fits every line into its slot and keeps the music and effects. You see the quote before you dub.

Discover AI dubbing

It speaks 55+ languages.Just like Voyager 1’s golden record.

Spanish from Spain and Latin America, British and American English, Catalan, Galician, Basque and many more, with a wide range of accents. And directions work in all of them.

In 1977, Voyager 1 carried a golden record into space with greetings in 55 languages. Today, your voice speaks 55+.

800+voices in the catalogue, with accents from every region
See every voice in the studio
  • Spanish
  • English
  • Korean
  • Norwegian
  • Galician
  • Greek
  • Basque
  • Yoruba
  • Bangla
  • Gujarati
  • Indonesian
  • Dutch
  • Finnish
  • Javanese
  • Malayalam
  • Turkish
  • Chinese
  • Afrikaans
  • Arabic
  • Catalan
  • Telugu
  • Bulgarian
  • Hausa
  • Hindi
  • Croatian
  • Japanese
  • Polish
  • Russian
  • Hebrew
  • Hungarian
  • Kannada
  • Marathi
  • Romanian
  • Slovak
  • Swahili
  • Tamil
  • Uzbek
  • Azerbaijani
  • Czech
  • Danish
  • Estonian
  • Kazakh
  • Slovenian
  • Swedish
  • Thai
  • Ukrainian
  • Vietnamese
  • Lithuanian
  • Latvian
  • Malay
  • Maltese
  • Nepali
  • Akan
  • Urdu
  • Persian
  • Filipino
  • Khmer
  • Odia
  • Punjabi
  • Cantonese
  • Assamese
  • Igbo
  • Georgian

Hear it in other languages

Simple pricing. Start free.

The same Voyager 1 on every plan: what changes is how many characters you get each month, how many voices you clone and the license. Cancel anytime.

The 40% applies to your first payment: the first month, or the whole first year if you pay yearly.

  • Free

    To try Voyager 1

    $0/mo
    Free
    • Voyager 1, like every plan
    • 800+ voices in 55+ languages
    • The full multi-voice studio
    • 1 voice clone
    • Personal use
    approx. 10 min of audio10,000 credits a month
    Start for free
  • Basic

    To start publishing

    $8.40
    $5.04/mo
    $60.48 for the first year instead of $100.80, plus VAT
    • Everything in Free
    • Commercial use
    • 3 voice clones
    • Dubbing without the logo
    • High queue priority
    approx. 103 min of audio100,000 credits a month
    Choose Basic
  • Plus

    Popular

    To create every week

    $15.40
    $9.24/mo
    $110.88 for the first year instead of $184.80, plus VAT
    • Everything in Basic
    • 10 voice clones
    • Review links, no account needed
    approx. 206 min of audio200,000 credits a month
    Choose Plus
  • Pro

    For professionals

    $69.30
    $41.58/mo
    $498.96 for the first year instead of $831.60, plus VAT
    1.2Mcredits a month
    approx. 1,230 min of audio6× the volume of Plus
    Includes
    • Everything in Plus
    • 30 voice clones
    • Live shared projects
    • Shared credits across your company
    Choose Pro
Built for production

Reliable, fast and with a verifiable origin.

  • 0 / 480

    sentences with no skips, repeats or made-up words.

  • ≈1 s

    per short sentence, watermark included. And up to 10,000 characters in a single call.

  • 48 kHz

    Broadcast quality, ready to air.

  • C2PA

    Inaudible watermark and Content Credentials on every clip.

Ready for where it airs.

MP3 or the 24-bit stereo 48 kHz WAV master, mastered for every destination. Plus 16 and 8 kHz for telephony.

  • Cinema−24 LUFS
  • TV−23 LUFS
  • YouTube−14 LUFS
  • Podcast−16 LUFS
  • AudiobookACX
  • Radio−13 LUFS

Voices with a known origin

Every Voyager 1 voice has documented provenance: synthetic voices built from our own dataset, recorded by professional voice actors who were paid for it, and from public datasets licensed for commercial use.

Audio is generated with an inaudible watermark and Content Credentials (C2PA), so its origin can be verified. Designed in line with the EU AI Act.

Hosted in Europe.

Speech is generated on GPU servers in the EU, and projects and audio are stored in the EU.

Audio credentialsC2PA
take-01.wav
Engine
Voyager 1
Voice provenance
Documented
Watermark
Inaudible
Content Credentials
C2PA
Framework
EU AI Act
Verifiable origin
Who we are

Voicefinder is a Spanish company that has spent years as one of Europe’s reference marketplaces for hiring professional voice talent.

Thousands of hours of human voice-over delivered to brands, studios and agencies set our bar for quality. Voyager 1 brings that bar to an advanced AI engine, built around what our clients kept asking for: control over every aspect of the performance.

For developers: your integration, live this afternoon

A clean, documented REST API, with up to 10,000 characters in a single call. Tags aren’t billed.

Read the docs
POST · /api/v1/text-to-speech
curl -X POST https://api.voicefinder.io/v1/text-to-speech/VOICE_ID \
-H "x-api-key: vf_your_key" \
-d '{"text": "[ironic] Oh, brilliant. [sigh] This was going to go great."}'
MCP

One connector. The whole studio.

Claude, Cursor, ChatGPT or your own agent connect to the Voicefinder MCP and do what you do in the studio: cast, direct, quote, generate and mix. Always quoted before anything is spent. Tags are never billed.

Claude Code · MCP
claude mcp add --transport http voicefinder
https://api.voicefinder.io/mcp
Connect your agent
  1. Your agentClaude · Cursor · ChatGPT · yours
  2. studio_voicesCasts from 800+ voices
  3. studio_apply_scriptScript, tags, intensity, effects, spaces
  4. studio_estimateQuote before anything is spent
  5. studio_generateTakes, charged once
  6. studio_mixMusic, master, 48 kHz
  7. Finished mixSigned with AudioSeal + C2PA

Stop generating voices. Start directing them.

Voyager 1. Your voice, further.