Conversational agents
Your agent replies without the silence that gives a machine away, in your brand’s voices and languages.
Voice agents
The real-time voice modelEarly access
Voice in about 100 milliseconds
median time to first audio, measured on the serverReal-time TTS for voice agents, assistants and phone lines. The same voices and the same quality as Voyager 1, speaking in about 100 ms.
Same voice, new speed
Many fast models trade quality for speed. Pulsar 1 doesn’t: it’s the same model as Voyager 1, built to respond. There’s no watered-down version of your voice.
What it shares with Voyager 1
What changes
to first audio than Voyager 1: Pulsar 1 starts speaking in about 100 ms.
Streaming audio: the first chunk can arrive at the first comma.
Pulsar 1 costs less than Voyager 1. We’ll publish the price right here at launch.
Latency under load
Latency with a single request tells you little. We measured time to first audio with 1, 4, 8, 16, 24, 32 and 48 conversations at once, and the median never went above 113 ms.
Measured on the server on 16 Oct 2026: median and 95th percentile of time to first audio at each load level. Network and your application are not included. The p95 is the time that 95 out of 100 responses come in under.
Demo
Real Pulsar 1 audio, in Spanish, across three sample calls: a dental clinic, a garage and an online store. Every reply shows its time to first audio, measured on the server; interrupt it and it stops to listen.
Audio by sentence: the first chunk can arrive at the first comma, without waiting for the end of the text.
Send cancel with the turn’s context_id and it stops speaking right away.
The same emotion tags as Voyager 1: [upbeat], [hushed]…
Hola, Lucía. Soy Clara, de la clínica dental Alba. ¿En qué te puedo ayudar?
Hi, Lucía. This is Clara, from Alba Dental Clinic. How can I help you?
Hola, Clara. Tenía cita el jueves, pero me ha surgido un lío en el trabajo y no voy a poder ir.
Hi, Clara. I had an appointment on Thursday, but something’s come up at work and I can’t make it.
[serene] Vale, entiendo lo que me cuentas. [comforting] Lo miramos ahora mismo y lo dejamos solucionado.
Okay, I understand what you’re telling me. We’ll look at it right now and get it sorted.
¿Podría ser el martes por la mañana?
Could we do Tuesday morning?
[upbeat] Perfecto, ya tienes la cita confirmada para el martes a las diez.
Perfect, your appointment is confirmed for Tuesday at ten.
Real Pulsar 1 audio, in Spanish, with the English translation underneath. On each reply, the time to first audio, measured on the server. Hit «Stop» while it speaks to see the cancel.
For developers
Open a WebSocket, send text with speak and get audio back sentence by sentence. To cut it off, cancel. That’s it.
speak · flush · cancelThree messages: speak, flush what’s pending, stop.
context_idEach turn has its own: cut one off without closing the connection.
μ-law · A-lawReady for telephony. PCM 16-bit and PCM float too.
24 kHzNative, resampled to whatever rate your system uses.
The Voicefinder REST API works with the most popular text to speech SDKs: change the base URL and the key, and you’re done.
How to migrateimport asyncio, json, os, websockets URL = os.environ["PULSAR_WS_URL"] # pending: arrives with early access async def main(): async with websockets.connect(URL) as ws: # authentication: pending await ws.send(json.dumps({ "type": "speak", "context_id": "turn-1", "model_id": "pulsar", # provisional "voice_id": "VOICE_ID", "text": "[upbeat] Hi! How can I help?", })) await ws.send(json.dumps({"type": "flush", "context_id": "turn-1"})) async for chunk in ws: player.write(chunk) # first audio in ~100 ms asyncio.run(main())Use cases
Your agent replies without the silence that gives a machine away, in your brand’s voices and languages.
Voice agentsμ-law and A-law for the phone system: menus that answer instead of making people wait.
AI receptionistSpoken answers inside your product, in 55+ languages.
Characters that answer on the spot, with emotion: [hushed], [upbeat]…
Instant read-aloud for anyone who can’t, or would rather not, read the screen.
Models
One model, two jobs: one produces, the other converses.
The name
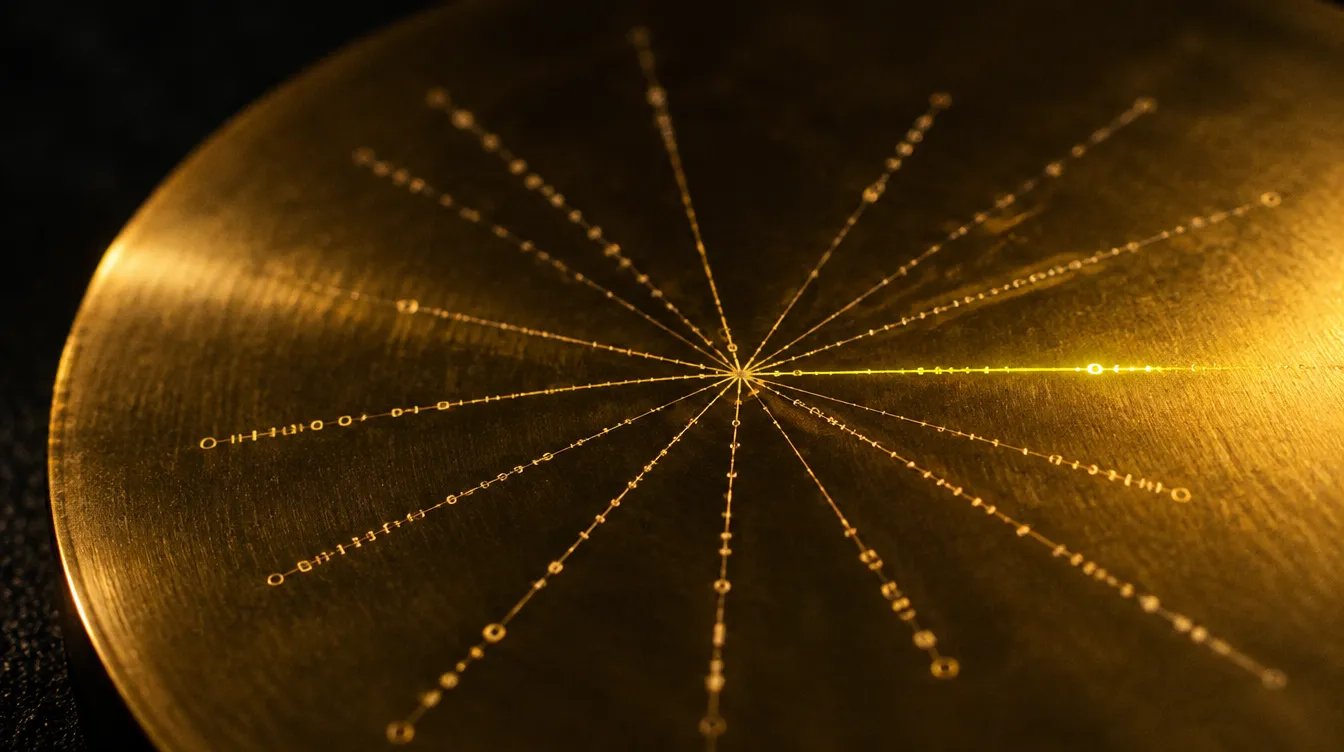
The Voyager 1 Golden Record carries a pulsar map: fourteen stars that tell anyone who finds it where the probe came from. Pulsars spin hundreds of times a second and sweep space with two beams of light, like a lighthouse.
They’re the most precise clocks in the universe. That’s why our fastest model is named after them.
Meet Voyager 1FAQ
Missing one? Ask us when you request early access.
Pulsar 1 is Voicefinder’s low latency text to speech: the same model as Voyager 1, built to respond. It starts speaking in about 100 ms and streams audio over WebSocket, sentence by sentence, for voice agents, assistants, telephony, games and real-time apps.
Median time to first audio is about 100 ms: between 93 and 113 ms with 1 to 48 concurrent conversations, measured on the server on 16 Oct 2026. A typical agent sentence arrives in full in 95-125 ms. Your network and your application come on top.
No. Pulsar 1 uses the same voices, the same 55+ languages, the same emotions and the same voice quality as Voyager 1. What changes is how the audio arrives: streamed sentence by sentence instead of as one complete file.
Yes. Besides PCM 16-bit and PCM float, Pulsar 1 outputs μ-law and A-law, the telephony formats, at a native 24 kHz or resampled to whatever rate your phone system uses.
Your app sends cancel with that turn’s context_id and Pulsar 1 stops speaking. The connection stays open and the next turn starts with a new context_id.
Less per character than Voyager 1. We’ll publish the price on this page when Pulsar 1 launches; in the meantime, request early access and we’ll walk you through the terms.
Pulsar 1 is in early access: request it and we’ll get in touch to set you up. Meanwhile, you can try the same voices with Voyager 1 in the studio or through the API.
Voyager 1’s voices at the speed of a conversation. Pulsar 1 is in early access.