TTS Bench is an independent benchmark that tests 29 commercial text-to-speech APIs on the same sentences, with the same metrics. Voyager 1, Voicefinder's text-to-speech model, joined it on 18 November 2026, the day it launched. This post shows where it landed, how the benchmark measures, and where other models are still ahead.
The results in three lines
- Naturalness (NAQ): Voyager 1 ranks 18th of 29, ahead of ElevenLabs Eleven v4 (19th) and Eleven v4 Turbo (21st).
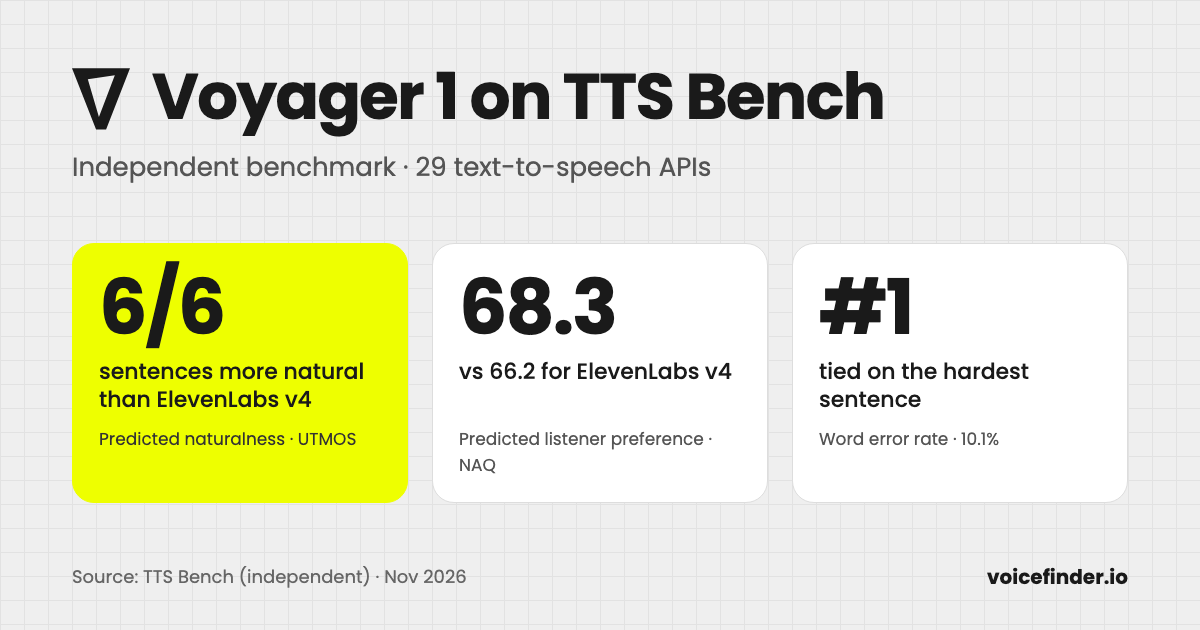
- Predicted naturalness (UTMOS): Voyager 1 scores higher than ElevenLabs v4 on all 6 sentences, in English, French and Spanish.
- The hardest sentence: Voyager 1 is tied for 1st place on word error rate (10.1%), with Fish Audio Drama 3 and xAI. ElevenLabs v4 gets 14.1%.
What TTS Bench is
TTS Bench is run by Tym Rabchuk (@5uck1ess on GitHub). Voicefinder does not fund, run or advise it. It started as a benchmark of local TTS models and now has a separate board for paid cloud APIs, where Voyager 1 sits next to ElevenLabs, OpenAI, Gemini, Cartesia, Fish Audio, MiniMax and others.
Every API reads the same 6 sentences (4 in English, 1 in French, 1 in Spanish), 3 times each, with its default voice. A second round tests voice cloning. The audio, the scripts and the scores are public in the repository, so anyone can check them.
How it measures
- NAQ is the benchmark's main naturalness score: the chance, from 0 to 100, that a listener picks a model over a typical bench model in a blind A/B test. It comes from a model trained on the blind votes of the benchmark's own listening arena.
- UTMOS is naturalness predicted by an automatic model, from 1 to 5. The benchmark notes that it mostly reflects how clean the audio is.
- WER (word error rate) is the share of words that a speech recogniser does not get right when it transcribes the audio. Lower is better.
- SIM measures how close a cloned voice is to the original. Higher is better.
Naturalness: ahead of ElevenLabs on both scores
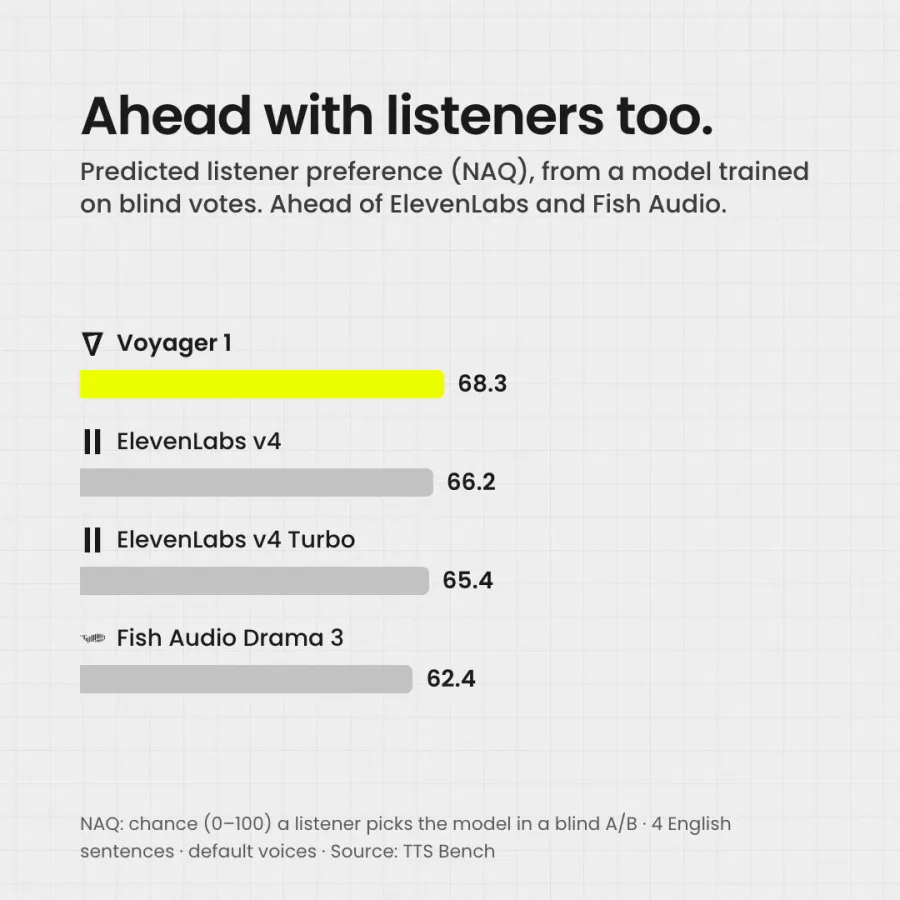
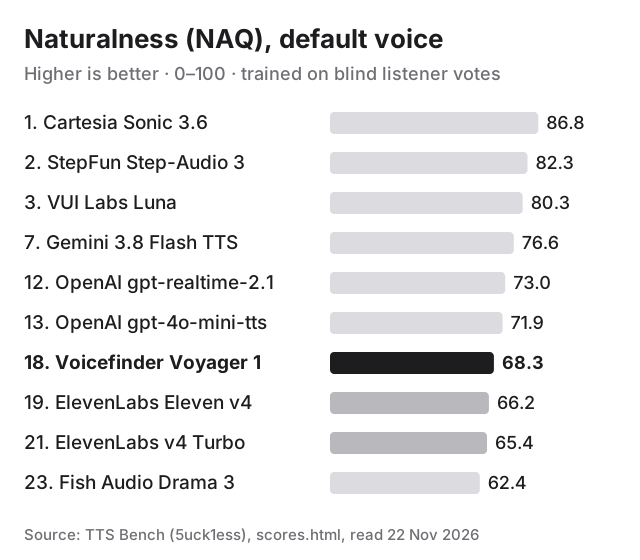
On NAQ, Voyager 1 scores 68.3 and ElevenLabs v4 scores 66.2. Seventeen models are ahead of both, led by Cartesia Sonic 3.6 (86.8). We publish that too.
NAQ is scored on the 4 English sentences only. Sentence by sentence, Voyager 1 is ahead of ElevenLabs v4 on 3 of the 4; ElevenLabs v4 is ahead on sentence 2.
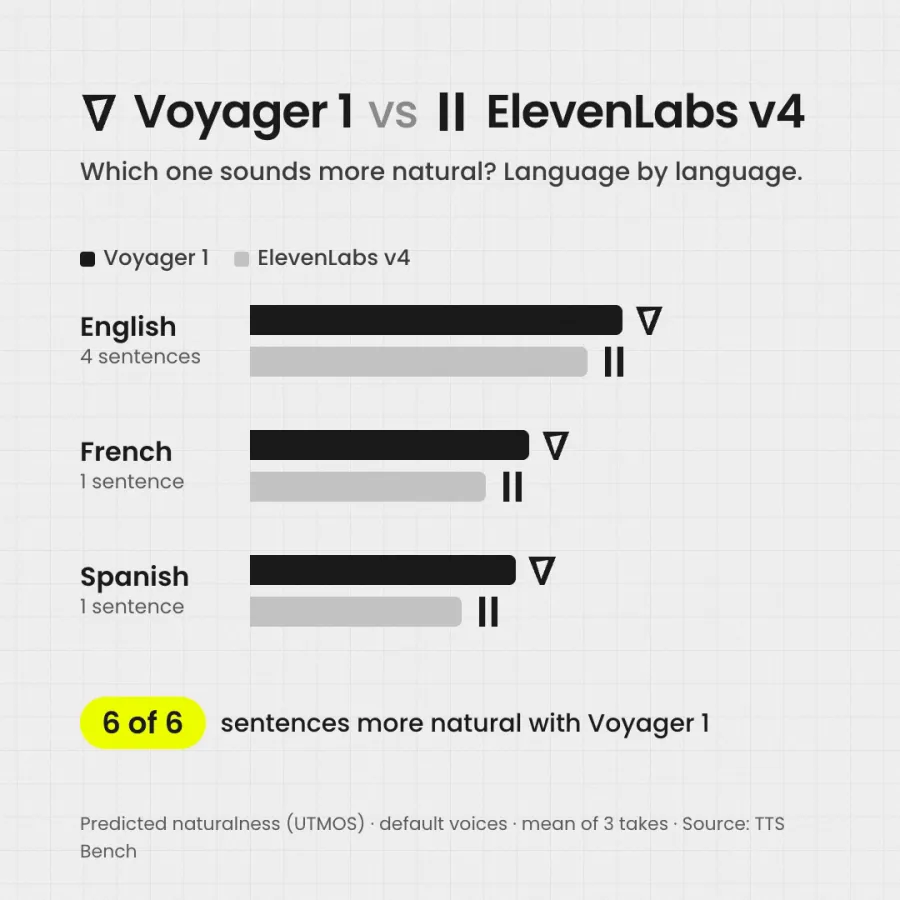
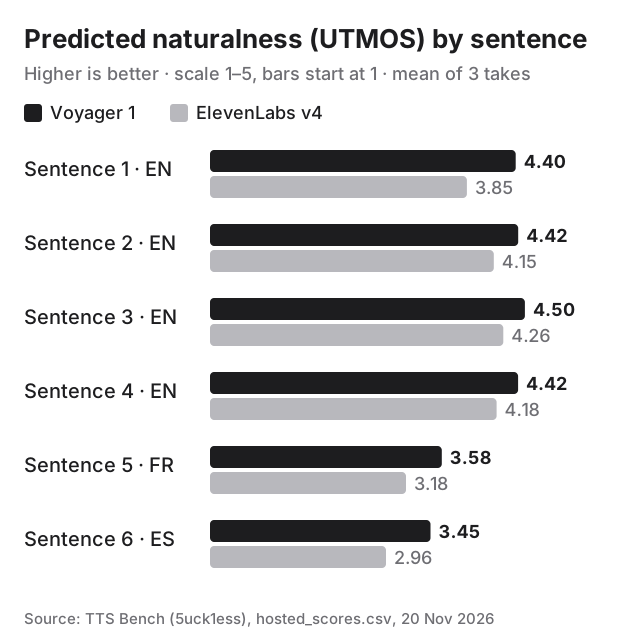
On UTMOS, Voyager 1 is ahead of ElevenLabs v4 on every sentence, and ahead of Eleven v4 Turbo as well. The widest gaps are on sentence 1 (4.40 against 3.85) and on the Spanish sentence (3.45 against 2.96).
The hardest sentence
Sentence 3 is the one that trips up most models. It is a single long line full of numbers and technical names:
“The Parakeet TDT zero point six billion parameter model achieves one point six nine percent word error rate on LibriSpeech test-clean, beating Whisper Large V3 at two point seven percent while running at over two thousand times realtime on a single GPU.”
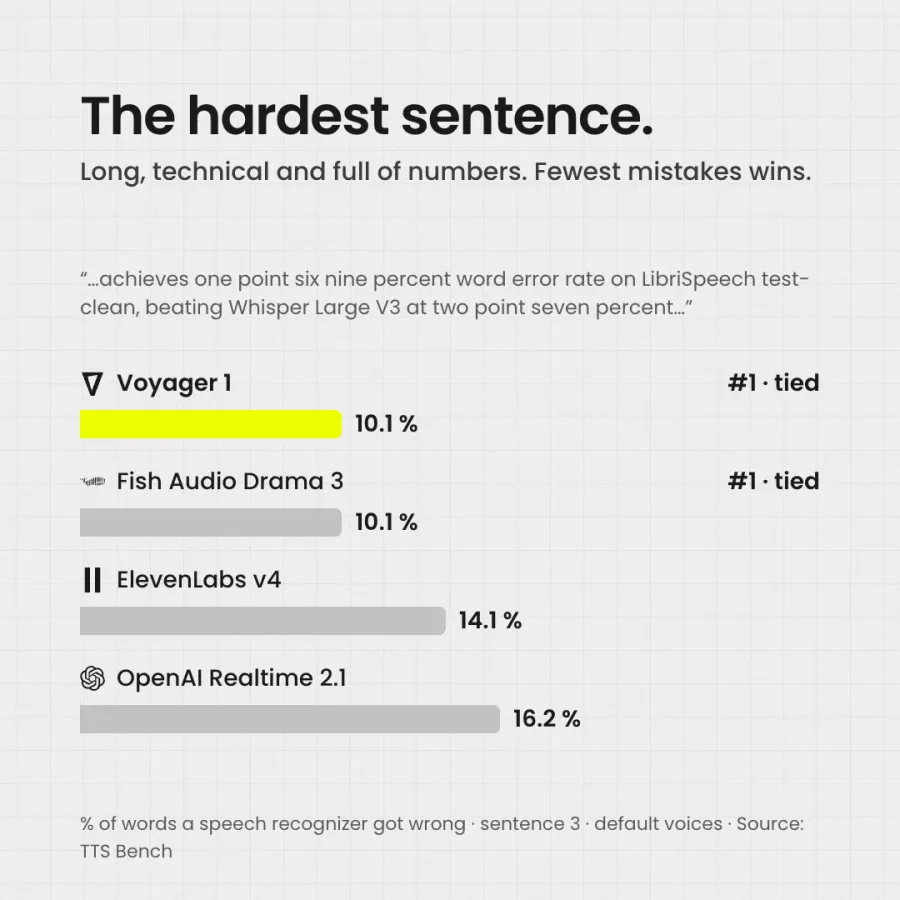
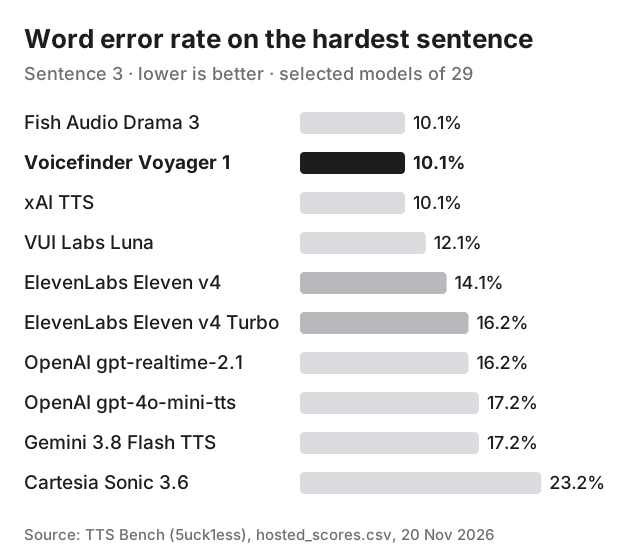
Voyager 1 shares 1st place with Fish Audio Drama 3 and xAI, at 10.1%. ElevenLabs v4 gets 14.1% and OpenAI gpt-realtime-2.1 gets 16.2%. Across all 6 sentences the gap is smaller: Voyager 1 ranks 7th (4.15%) and ElevenLabs v4 8th (4.21%).
Where others are ahead
- Overall naturalness: on NAQ, 17 models rank above Voyager 1. Cartesia, StepFun and VUI Labs lead.
- UTMOS across all 6 sentences: Voyager 1 ranks 17th of 29. gpt-4o-mini-tts and Fish Audio Drama 3 are ahead.
- French and Spanish: on the two non-English sentences, Fish Audio Drama 3 scores higher than Voyager 1 on UTMOS.
- Voice cloning: ElevenLabs v4 (0.765) and Cartesia (0.769) produce clones slightly closer to the original than Voyager 1 (0.753).
Two days after launch, that is where Voyager 1 stands. We will keep improving it, and the benchmark will show whether we do.
Listen for yourself
Numbers only go so far. The benchmark's Listen page plays every model on every sentence, and its blind TTS Voting Arena lets you vote without seeing model names. Those votes train NAQ.
Or try Voyager 1 with your own text: 800+ voices, 55+ languages with regional accents, and emotion tags you place sentence by sentence.
Try Voyager 1 free: 10,000 characters a month, no card. Launch offer: 40% off your first payment until 18 December 2026.
Data: TTS Bench, hosted_scores.csv from 20 November 2026 (UTMOS, WER, SIM; default voice, average of 3 takes) and the Scores page read on 22 November 2026 (NAQ). ElevenLabs, OpenAI, Gemini, Cartesia and the other names are trademarks of their owners. Voicefinder is not affiliated with TTS Bench or with the companies named.